
To reduce downtime across a feed mill, maintenance teams should prioritize equipment that stops production, detect deterioration early, and prepare repairs before failures occur.
For after-sales service technicians, the practical challenge is choosing which inspections prevent meaningful losses without adding unnecessary shutdowns, excessive servicing, or avoidable component replacements.
A useful program combines equipment-specific maintenance intervals, operating-condition checks, accessible spare parts, and service records that explain recurring faults rather than simply recording completed work.
The greatest gains come when technicians connect each maintenance task to a credible failure mode, an actionable warning sign, and a planned response window.
Which equipment deserves attention first?
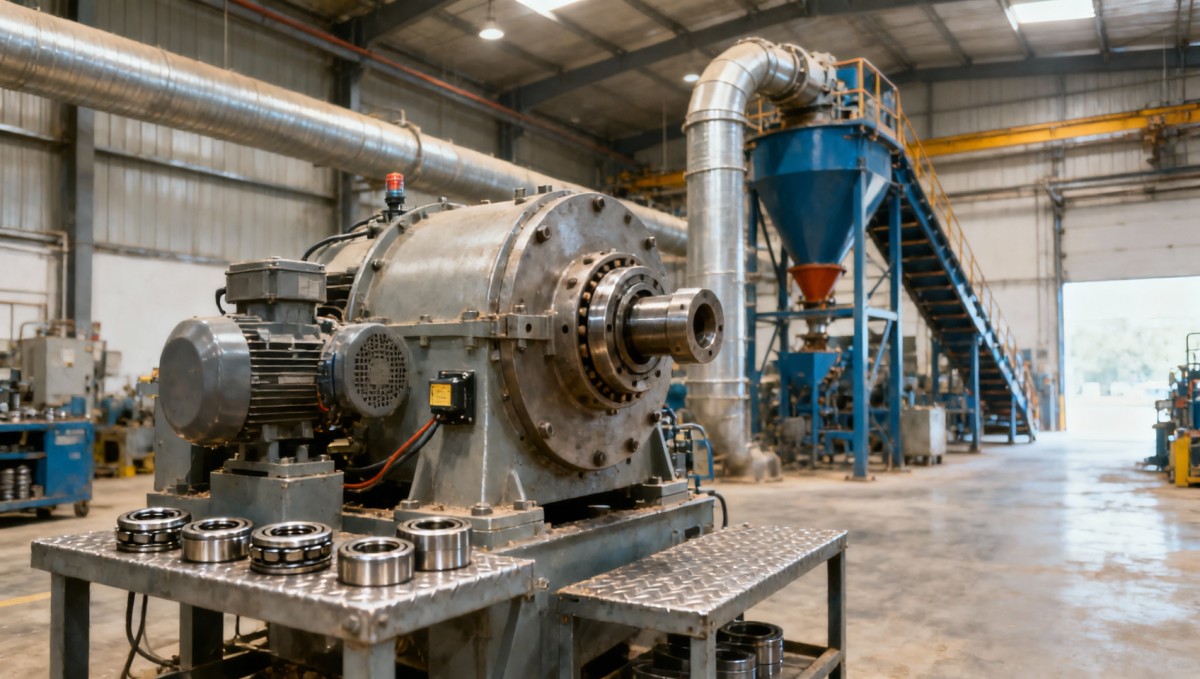
Start with the production route: receiving, conveying, grinding, batching, mixing, conditioning, pelleting, cooling, and dispatch. Identify where a single failure interrupts the entire line.
A pellet mill may attract attention because of its replacement cost, but an inexpensive bucket elevator bearing can cause an equally disruptive production stoppage.
Rank assets using three questions: What happens if this fails? How quickly can we detect deterioration? How long would restoration take with available resources?
Include safety and feed quality consequences alongside lost output. An overheating bearing, damaged screen, or inaccurate dosing system may require intervention before production stops.
Give higher priority to equipment without bypass routes, components with long delivery times, and assets whose failure could damage adjacent machinery or contaminate product.
Ask operators where they repeatedly clear blockages, reset overloads, or adjust tracking. These workarounds often reveal developing faults that formal maintenance records have missed.
Build the first maintenance schedule around these critical assets. Expanding gradually makes the program easier to sustain and prevents low-value tasks from consuming scarce technician time.
What should technicians check on each major machine?
Equipment-specific checks help technicians distinguish normal wear from faults requiring action. Use manufacturer instructions as the baseline, then adjust inspection frequency using documented operating experience.
On hammer mills, inspect hammer wear patterns, screen integrity, rotor condition, bearing behavior, and fastener security. Uneven wear can indicate feeding problems or rotor imbalance.
Compare grinding performance at similar throughput, ingredient characteristics, and screen configuration. Rising energy demand may reflect worn tooling, restricted airflow, or changes in incoming material.
On pellet mills, inspect die and roller wear, lubrication delivery, mounting security, and the OEM-specified die-to-roller setting. Avoid applying universal clearances across different machine designs.
Check conditioners and steam systems for leaking valves, failed traps, unstable supply, and buildup. Poor conditioning can create process interruptions that resemble mechanical pellet-mill faults.
For conveyors and elevators, examine belt tracking, tension, splice condition, chain elongation, buckets, and accessible bearings. Investigate recurring misalignment instead of repeatedly resetting protective switches.
On mixers, coolers, and dust extraction systems, check discharge operation, seals, airflow, buildup, and drive condition. Include magnets and screens that protect downstream equipment.
How often should preventive maintenance happen?
There is no reliable universal interval for every feed mill. Duty cycle, ingredient abrasiveness, moisture, ambient dust, equipment age, and loading all influence deterioration.
Combine calendar intervals with operating hours, throughput, and condition trends. A lightly used standby conveyor needs a different schedule from a continuously loaded production elevator.
The following framework provides a starting structure, not replacement instructions. Confirm actual frequencies, inspection methods, and acceptance limits against OEM documentation and site risk assessments.
Shorten intervals when inspections repeatedly uncover deterioration close to failure. Consider extending them cautiously when consistent records demonstrate stable condition and sufficient warning time.
Separate inspection frequency from replacement frequency. Checking a belt regularly does not mean replacing it regularly when its condition remains within approved service limits.
Lubrication deserves particular discipline: specify lubricant type, quantity, location, and method. Both insufficient lubrication and overgreasing can damage bearings and undermine an otherwise effective schedule.
Review intervals after changes in formulation, capacity, shift patterns, or operating conditions. A schedule developed for previous production demands may no longer provide adequate protection.
Which warning signs justify a planned intervention?
Condition checks become useful when they lead to decisions. Collecting temperature, vibration, or current readings without thresholds and responsibilities creates records without improving reliability.
Establish baseline readings when equipment is operating correctly. Record speed, load, product, and measurement location so later comparisons reflect actual deterioration rather than different conditions.
Bearing temperature trends can reveal developing problems, but temperature alone rarely identifies the cause. Check lubrication, alignment, loading, sensor reliability, and the surrounding environment.
Vibration monitoring can help identify imbalance, misalignment, looseness, and bearing deterioration. Interpretation requires suitable measurement methods and competent analysis, particularly on variable-speed or impact-heavy equipment.
Motor current and specific energy trends can expose increased resistance or declining process efficiency. Compare equivalent production conditions before concluding that mechanical wear is responsible.
Define escalation levels using OEM limits, baseline trends, and qualified assessment: investigate, schedule repair, or stop safely. Assign responsibility and a response deadline for each.
Never keep equipment running solely to reach a convenient shutdown when signs indicate imminent failure, fire risk, compromised protection, or an unacceptable feed safety risk.
How can service teams make shutdowns shorter and safer?
A planned shutdown saves time only when the job is ready. Confirm the fault, work scope, spare parts, tools, lifting arrangements, and technician availability beforehand.
Prepare a job package containing drawings, component specifications, required settings, isolation points, inspection criteria, and restart checks. Include realistic time allowances for access and cleaning.
Coordinate with production to empty or secure affected equipment and manage material remaining in bins, chutes, conditioners, or conveyors. Account for stored mechanical and thermal energy.
Apply site isolation and lockout procedures before intrusive work. Verify isolation, control stored energy, and use applicable permits for hot work, confined spaces, or elevated access.
Manage combustible dust throughout the job. Avoid cleaning methods that create airborne dust clouds, and follow site requirements for suitable equipment and ignition-source control.
Group compatible tasks within the same shutdown when access and resources allow. Avoid crowding work areas or extending a critical repair with unrelated maintenance.
After reassembly, verify guards, fasteners, alignment, lubrication, and protective devices. Follow the approved startup procedure, then confirm stable operation and acceptable product before normal production resumes.
Which spare parts actually reduce repair time?
Spare-parts planning should reflect failure consequences and replenishment time. Stocking many inexpensive items does little if one unavailable critical assembly keeps the line stopped.
For each critical asset, identify likely replacement components, their exact specifications, normal delivery times, and approved substitutes. Confirm compatibility against machine serial numbers and modifications.
Common candidates include bearings, seals, belts, coupling elements, sensors, and wear components. The correct stock quantity depends on installed population, consumption history, and supplier reliability.
Assess expensive assemblies separately. A spare gearbox or motor may be justified when delivery is lengthy, production losses are substantial, and substitution options are limited.
Build service kits around recurring jobs, including required gaskets, locking devices, and approved consumables. Missing small items can delay an otherwise fully prepared repair.
Store parts according to manufacturer requirements and check shelf life where applicable. Protect bearings, elastomers, electrical components, and lubricants from moisture, contamination, and unsuitable temperatures.
For after-sales support, agree how urgent parts are identified, dispatched, and technically verified. Clear escalation contacts prevent delays caused by repeated specification checks during emergencies.
What should service records reveal about repeat failures?
A useful service record connects symptoms, findings, corrective work, and operating results. “Bearing replaced” offers little guidance when the same position fails again next month.
Record the asset identifier, operating hours, fault symptoms, measured condition, failure location, installed parts, and relevant photographs. Distinguish confirmed causes from assumptions awaiting further investigation.
Capture elapsed time separately for diagnosis, isolation, parts waiting, active repair, and restart. This shows whether downtime comes primarily from equipment reliability or service delays.
Repeated failures justify a deeper review of alignment, lubrication delivery, contamination, installation practice, operating load, and component selection. Replacing the failed item alone may preserve the cause.
Include production and quality teams when investigating blockages, die plugging, or inconsistent throughput. Ingredient variation and process settings can generate symptoms that appear mechanical.
Close each significant repair with an effectiveness check after a defined operating period. Confirm that readings, output, and fault frequency improved under comparable production conditions.
Use these findings to update work instructions and service intervals. Shared records help different technicians recognize known problems without relying on one experienced colleague’s memory.
How do you prove the maintenance program is working?
Track unplanned downtime hours alongside scheduled maintenance hours. A program that simply relabels interruptions or expands servicing without improving availability has not demonstrated success.
Measure mean time between failures for consistently defined assets and mean time to repair using consistent boundaries. Review parts-waiting time separately to expose supply constraints.
Monitor emergency work, repeat failures, and completed critical inspections. High schedule compliance means little if inspections miss deterioration or corrective actions remain unresolved for weeks.
Normalize comparisons for operating hours, throughput, and major product changes. Otherwise, reduced downtime during a quiet production month may be mistaken for improved equipment reliability.
Estimate value using avoided lost contribution, reduced secondary damage, and lower emergency costs, then subtract added maintenance expenditure. Avoid treating every recovered hour as guaranteed sales.
Begin with one production bottleneck and establish its baseline before changing the maintenance approach. A focused trial makes practical benefits and implementation problems easier to identify.
Expand when the evidence supports it. The strongest program is one technicians can execute consistently, operators understand, and maintenance managers can improve using credible records.
Build maintenance around actionable failure risks
Preventive maintenance reduces feed mill downtime when teams detect credible warning signs early, prepare the right intervention, and remove the causes of recurring equipment failures.
Start with critical assets, establish practical inspection routes, define escalation rules, and prepare essential spares. Use each service visit to strengthen the next maintenance decision.
For after-sales technicians, success means fewer emergency callouts, shorter restoration windows, and reliable operation after handover. Every scheduled task should contribute clearly to those outcomes.
